Published

All published posts

2717 posts latest post 2026-11-11
Publishing rhythm
Oct 2026 | 30 posts

I spoke at python webconf in March 2022 about how I deploy this blog on a continuous basis.

Building this blog has brought me a lot of benefits. I have a set of custom curated notes to help describe a problem and how to solve it to me. At theis point it’s not uncommon to google an Issue I am having and finding my own blog with exactly the solution I need at the top.

I also bump into people from time to time that recognize me from the blog, its a nice conversation starter, and street cred.

The Talk #

The talk recently released on Youtube, you can watch it without having a ticket to the conference for free. There were a bunch of other talks that you should check out too!

https://youtu.be/JDZVjDCTKHE

rofi-network-manager by P3rf is a game-changer in its space. Excited to see how it evolves. A manager for network connections using bash, rofi, nmcli,qrencode.

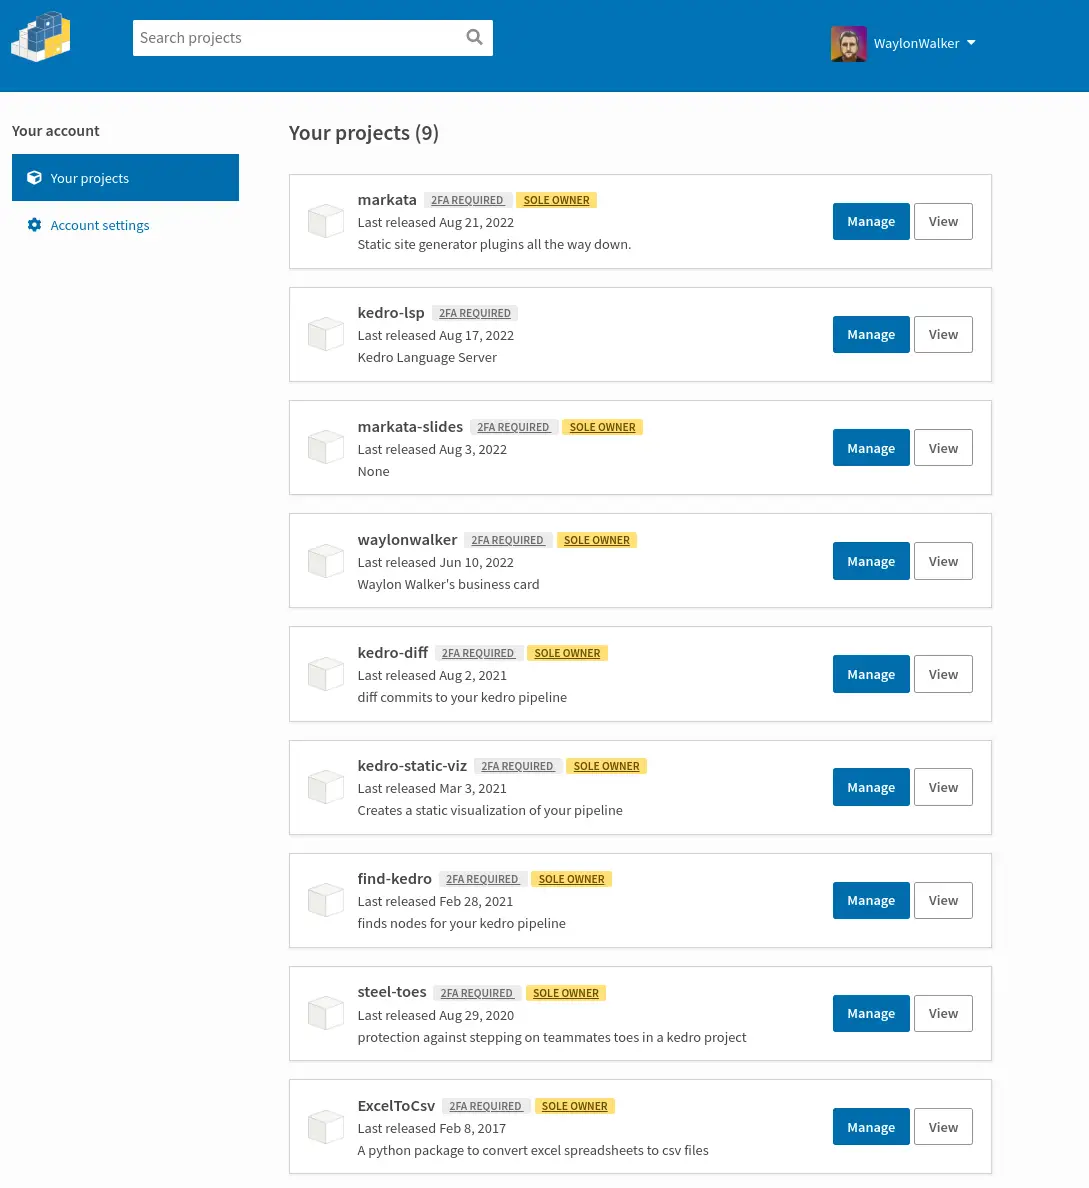
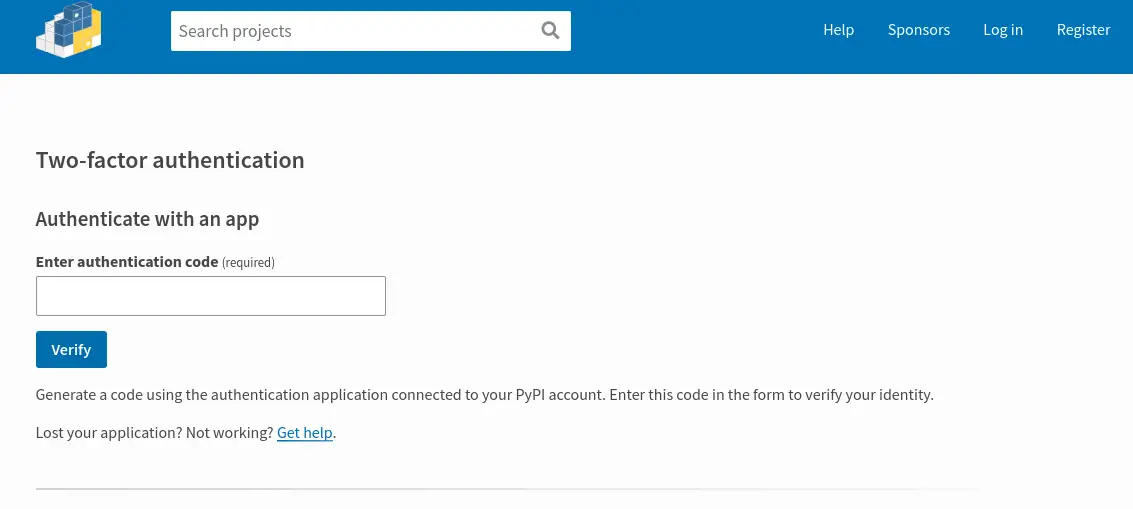
I got all the pypi packages that I own behind 2 factor authentication. 💪

Recently this really made it’s rounds in the python news since pypi was requiring critical package maintainers to have 2FA on and even offering them hardware tokens to help them turn this on.

I feel like this caused a bit of confusion as turning on 2FA does not mean that you need to do anything different to deploy a package, and it DOES NOT require a hardware token. You can continue using your favorite 2FA app.

You might wonder what this means for my projects. It means that to edit any sensitive content such as pull a new api token, add/remove maintainers, or deleting a release I need to use a TOPT (time based one time password) application such as Google Authenticator, Microsoft Authenticator, Authy, or FreeOTP.

This has very little change to my overall workflow as my CI system still automatically deploys for me with the same api token as before.

This is one small thing that maintainers can do to prevent supply chain attacks on their projects that they put so much work into.

Login #

When I log in I now get this extra screen asking for an auth token.

pypi-2fa-code.webp

My packages #

Once I turned on 2FA for my account I could then turn on 2FA requirement for each project. I am not sure how much safety there is in pypi, it might require all maintainers to have it turned on before it allows packages to have it turned on.

my-pypi-packages-aug-2022.webp

Once turned on it requires anyone who maintains the project to have 2FA on to be able to edit any sensitive content.

I was on Talk Python

After years of listening to talkpython.fm I had the honor to be part of episode-337 to talk about Kedro for maintainable data science. I was quite nervous to talk on a show that I helped shape my career in such a profound way. I started my journey towards software engineering near Michaels first few episodes. His discussions with such great developers over the years has made an huge impact on my skill. It has always given me great advice and topics to go deeper on. During the episode I tried my best to let Yetu and Ivan take the spotlight as the maintainer and chime in with my experience as a user of kedro. Video Version https://youtu.be/WTcjvwkXoY0 Michael made the call available on youtube as well as the audio only podcast
1 min read

I just love how some features of vim are so discoverable and memorable once you really start to grasp it. Sorting and uniqing your files or ranges is one of those examples for me.

" sort the file
:sort
" sort the file only keeping unique lines
:sort u


" sort a range
:'<,'> sort
" sort a range only keeping unique lines
:'<,'> sort u

I recently used this to dedupe my autogenerated links section for rich-syntax-range-style. More often I am using it to sort and uniqify objects like arrays and lists.

Here is what the markdown looks like.

* [py-tree-sitter](https://github.com/tree-sitter/py-tree-sitter)
* [rich](https://github.com/Textualize/rich)
* [@textualizeio](https://twitter.com/textualizeio)
* [rich](https://github.com/Textualize/rich)
* [another post](https://waylonwalker.com/designing-kedro-router)
* [print-register-pipelines](https://screenshots.waylonwalker.com/print-register-pipelines.webp)
* [rich](https://github.com/Textualize/rich)
* [console-print-register-pipelines](https://screenshots.waylonwalker.com/console-print-register-pipelines.webp)
* [rich](https://github.com/Textualize/rich)
* [syntax-print-register-pipelines](https://screenshots.waylonwalker.com/syntax-print-register-pipelines.webp)
* [rich](https://github.com/Textualize/rich)
* [syntax-print-register-pipelines-highlight-line](https://screenshots.waylonwalker.com/syntax-print-register-pipelines-highlight-line.webp)
* [py-tree-sitter](https://github.com/tree-sitter/py-tree-sitter)

Then typing vap:sort u yields a uniqly sorted list of links.

* [@textualizeio](https://twitter.com/textualizeio)
* [another post](https://waylonwalker.com/designing-kedro-router)
* [console-print-register-pipelines](https://screenshots.waylonwalker.com/console-print-register-pipelines.webp)
* [print-register-pipelines](https://screenshots.waylonwalker.com/print-register-pipelines.webp)
* [py-tree-sitter](https://github.com/tree-sitter/py-tree-sitter)
* [rich](https://github.com/Textualize/rich)
* [syntax-print-register-pipelines-highlight-line](https://screenshots.waylonwalker.com/syntax-print-register-pipelines-highlight-line.webp)
* [syntax-print-register-pipelines](https://screenshots.waylonwalker.com/syntax-print-register-pipelines.webp)

Today I’ve been playing with py-tree-sitter a bit and I wanted to highlight match ranges, but was unable to figure out how to do it with rich, so I reached out to @textualizeio for help.

https://twitter.com/_WaylonWalker/status/1562469770766589952

While waiting for that reply let’s show how we got this far.

imports #

Lets import all the classes that we need from rich and setup a console to print to.

from rich.console import Console
from rich.syntax import Syntax
from rich.style import Style

console = Console()

some code #

Now we need some code to highlight. I am going to rip my register_pipeline from another post.

code = '''
from find_kedro import find_kedro

def register_pipelines(self) -> Dict[str, Pipeline]:
    """Register the project's pipeline.
    Returns:
        A mapping from a pipeline name to a ``Pipeline`` object.
    """
    return find_kedro()
'''

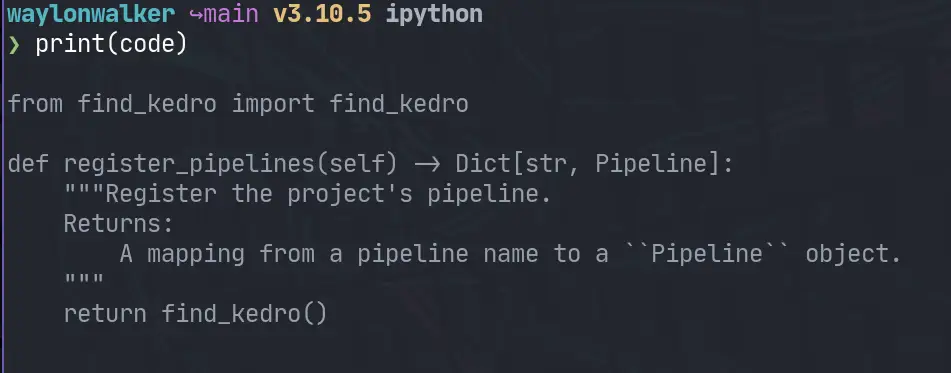
print #

We could simply print out the code we have as a variable, but thats a bit hard to read.

print-register-pipelines.webp

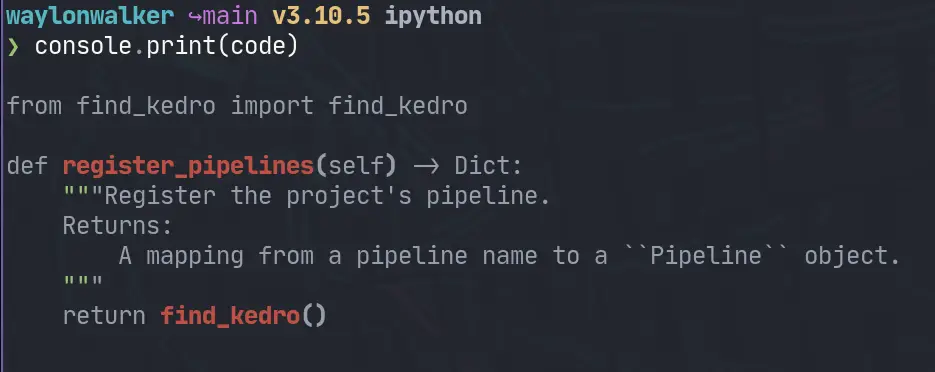
console.print #

printing with rich’s console makes it a little better, but not much by default.

console-print-register-pipelines.webp

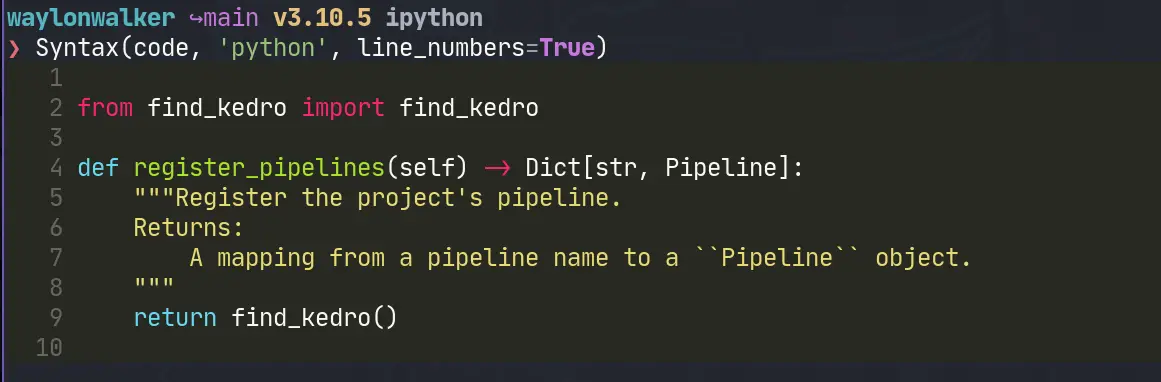
Syntax #

We can pull from rich’s syntax module to really pretty this up.

syntax = Syntax(code, 'python', line_numbers=True)
console.print(syntax)
syntax-print-register-pipelines.webp

Now we are getting some really impressive print outs right in the terminal!

note that I have ipython set to use rich, you will need to console.print() in scripts

highlight lines #

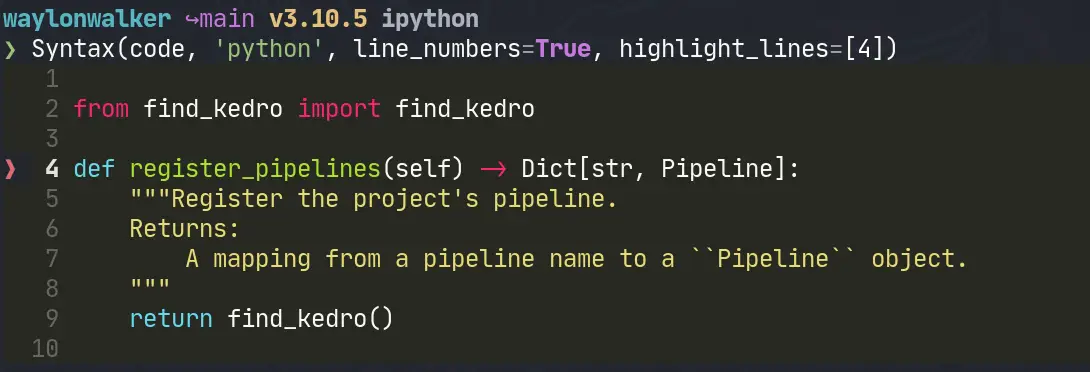
Now we can start highlighting lines right when we initialize our Syntax instance. It looks ok. It’s not super visible, but more importantly its not granular enough. I want to highlight specific ranges like the word register_pipelines.

syntax = Syntax(code, 'python', line_numbers=True, highlight_lines=[4])
console.print(syntax)
syntax-print-register-pipelines-highlight-line.webp

This hows the line, but still is not very accurate.

highlight text #

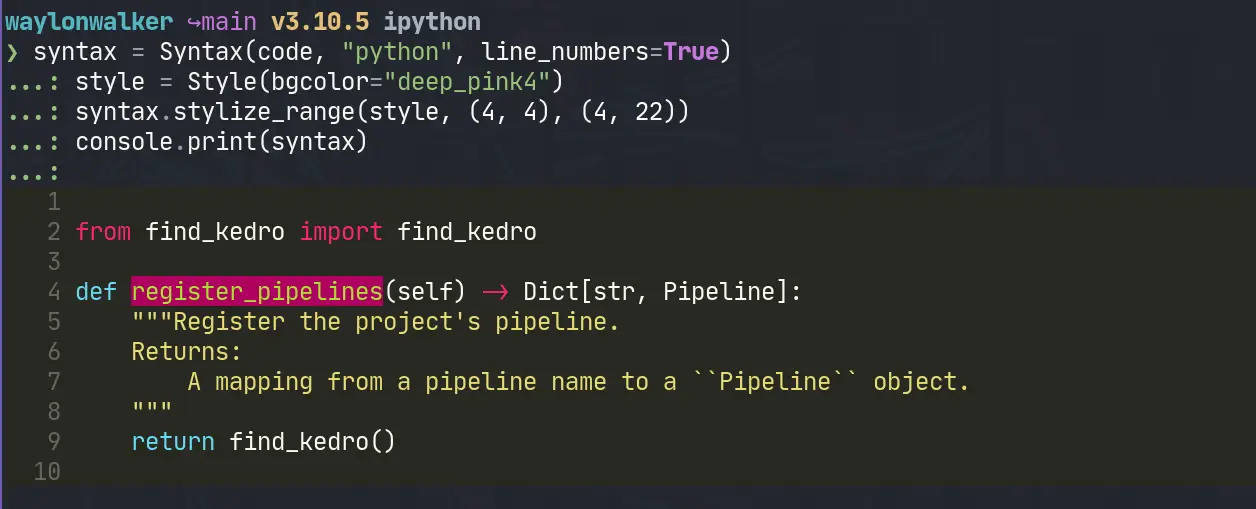
[@textualizeio] got back to me, let’s see if What we can do with stylize_range!

https://twitter.com/textualizeio/status/1562487302274043904

syntax = Syntax(code, 'python', line_numbers=True)
style = Style(bgcolor='deep_pink4')
syntax.stylize_range(style, (4, 4), (4, 22))
console.print(syntax)

This gives us the final result we are looking for, we can easily see what is being targeted here. In this case the function name register_pipelines.

syntax-highlight-range-register-pipelines.webp

This turns out to be exacly what I am looking for. Now I have an easy way to print out highlighted code wtih my py-tree-sitter query results.

How to vimgrep over hidden files.

I needed to delete all build pipeline steps that were named upload docs. I currently have about 60 projects running from the same template all running very similar builds. In the past I’ve scripted out migrations for large changes like this, they involved writing a python script that would load the yaml file into a dictionary, find the corresponding steps make the change and write it back out.

Today’s job was much simplar, just delete the step, were all steps are surrounded by newlines. My first thought was to just open all files in vim and run dap. I just needed to get these files:positions into my quickfix. My issue is that all the builds reside within hidden directories by convention.

The issue #

variability

After searching through all the projects it was clear that all the steps were in their own paragraph, though I was not 100% confident enough to completely automate it, and the word upload docs was in the paragraph.

some were a two liner

- name: upload docs
  script: aws s3 ...

Some had a variation in the name

- name: upload docs to s3
  script: aws s3 ...

some were more than 2 lines.

- name: upload docs
  script: |
    aws s3 ...

some used a different command.

- name: upload docs
  script: |
    python ...

Templates are great #

but they change

Templates are amazing, and tools like cookiecutter and copier are essential in my workflow, but those templates change over time. Some things are a constant, and others like this one are an ever evolving beast until they are tamed into something the team is happy with.

vimgrep over hidden files #

I know all the files that I care to search for are called build.yml, and they are in a hidden directory.

:args `fd -H build.yml`
:vimgrep /upload docs/ ##

Once opened as a buffer by using args, and a handy fd command I can vimgrep over all the open buffers using ##

Open buffers are represented by ##

Now I can just dap and :cnext my way through the list of changes that I have, and know that I hit every one of them when I am at the end of my list. And can double check this in about 10s by scrolling back through the quickfix list.

Vim points achieved #

You’re not a true vim enthusiast until you have spent 10 minutes writing a blog post about how vim saved you 5 minutes. Check out all the other times this has happened to me in the vim tag.

image from Dall-e

a sprinter edging out his opponent by Dall-e

It’s about time to release Markata 0.3.0. I’ve had 8 pre-releases since the last release, but more importantly it has about 3 months of updates. Many of which are just cleaning up bad practices that were showing up as hot spots on my pyinstrument reports

Markata started off partly as a python developer frustrated with using nodejs for everything, and a desire to learn how to make frameworks in pluggy. Little did I know how flexible pluggy would make it. It started out just as my blog generator, but has turned into quite a bit more.

Over time this side project has grown some warts and some of them were now becoming a big enough issue it was time to cut them out.

Let’s compare #

I like to use my tils articles for examples and tests like this as there are enough articles for a good test, but they are pretty short and quick to render.

mkdir ~/git/tils/tils
cp  ~/git/waylonwalker.com/pages/til/ ~/tils/tils -r
cd ~/git/tils/tils

running tils on 0.2.0 #

At the time of writing this is the current version of markata, so just make a new venv and run it.

python3 -m venv .venv --prompt $(basename $PWD)
pip install markata
markata clean
markata build

cold tils: 14.523 warm tils: 1.028

running tils on 0.3.0b8 #

python3 -m venv .venv --prompt $(basename $PWD)
# --pre installs pre-releases that include a b in their version name
pip install markata --pre
markata clean
markata build

cold tils: 11.551 (+20%) warm tils: 0.860 (+16%)

pyinstrument #

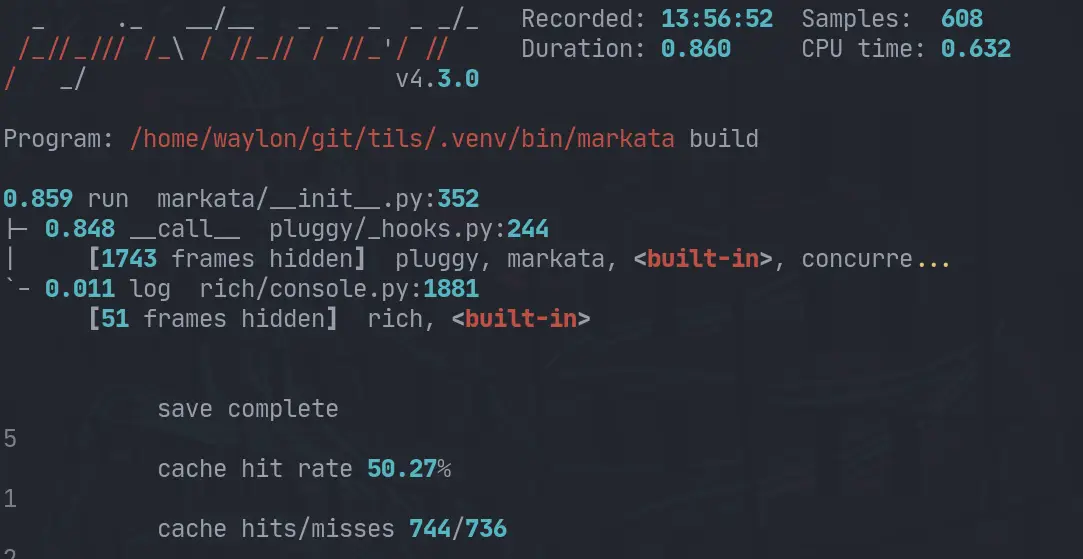
These measurements were taken with pyinstrument mostly out of convenience since there is already a pyinstrument hook built in, but also because I like pyinstrument.

pyinstrument-markata==0.3.0b8-tils-hot.webp

Here is the pyinstrument report from the last run.

My Machine #

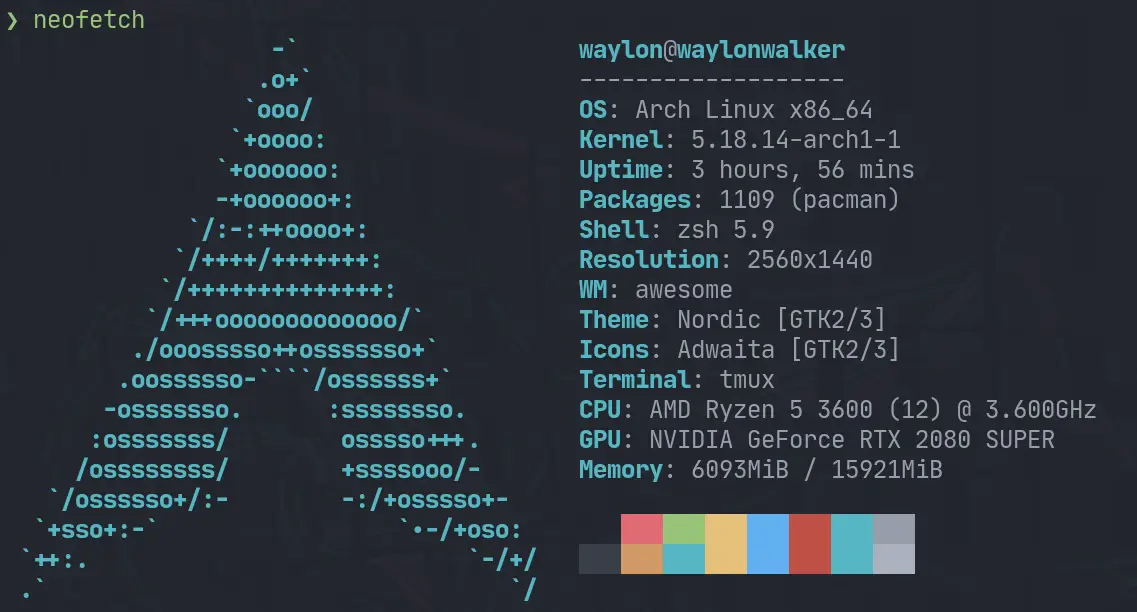
This comparison was not very exhaustive. It was ran on my pretty new to me Ryzen 5 3600 machine.

neofetch-8-21-2022.webp

The changes #

Most of these changes revolve in how the lifecycle is ran. It was trying to be extra cautious and run previous steps for you if it thought it might be needes, in reality it was rerunning a few steps multiple times no matter what.

The other thing I turned off by default, but can be opted into, is beautifulasoup’s prettify. That was one of the slower steps ran on my site.

0.3.0 #

It should be out by the time you see this, I wanted to compare the changes I had made and make sure that it was still making forward progress and thought I would share the results.

Deliberative #

People exceptionally talented in the Deliberative theme are best described by the serious care they take in making decisions or choices. They anticipate obstacles.

I am risk-adverse. I want everything well thought out and calculated before I make any sort of change. I have never gambled in my life and just the thought of it makes me anxious.

Aim it #

I can use this as a strength to plan out potential issues and prevent them. I do this quite often with my role in infrastructure.

I need to make sure that I use deadlines to keep this as a strength and not hinderence.

Automation #

One of the biggest ways that I utilize this skill is automation. I am all about automating things, not just because I don’t want to do the manual work, but I am not sure when I am going to need to do something again.

Check out archlinux and their project aur. ⚠️⚠️Experimental aur. git mirror⚠️⚠️ (read-only mirror)

A common meta thing that I need in python is to find the version of a package. Most of the time I reach for package_name.__version__, but that does not always work.

but not all projects have a __version__ #

In searching the internet for an answer nearly every one of them pointed me to __version__. This works for most projects, but is simply a convention, its not required. Not all projects implement a __version__, but most do. I’ve never seen it lie to me, but there is nothing stopping someone from shipping mismatched versions.

If you maintain a project ship a __version__ #

I appreciate it

While its not required its super handy and easy for anyone to remember off the top of their head. It makes it easy to start debugging differences between what you have vs what you see somewhere else. You can do this by dropping a __version__ variable inside your __init__.py file.

## __init__.py
__version__ = 1.0.0

SO #

stack overflow saves the day

Special thanks to this Stack Overflow post for answering this question for me.

So what do you do… #

importlib

Your next option is to reach into the package metadata of the package that you are interested in, and this has changed over time as highlighted in the stack overflow post.

for Python >= 3.8:

from importlib.metadata import version

version('markata')
# `0.3.0.b4`

I only really use python >= 3.8 these days, but if you need to implement it for an older version check out the stack overflow post.

Another option.. #

use the command line

Another common option uses pip at the command line.

❯ pip show markata
Name: markata
Version: 0.3.0b4
Summary: Static site generator plugins all the way down.
Home-page: https://markata.dev
Author: Waylon Walker
Author-email: [email protected]
License: MIT
Location: /home/waylon/git/waylonwalker.com/.venv/lib/python3.11/site-packages
Requires: anyconfig, beautifulsoup4, checksumdir, diskcache, feedgen, jinja2, more-itertools, pathspec, pillow, pluggy, pymdown-extensions, python-frontmatter, pytz, rich, textual, toml, typer
Required-by:

And if the package implements a command line its common to ship a version command such as --version or -V.

❯ markata --version
Markata CLI Version: 0.3.0.b4

Why did I need to do this? #

Well we have a cli tool that wraps around piptools and we wanted to include the version of piptools in the comments that it produces dynamically. This is why I wanted to dynamically grab the version inside python without shelling out to pip show. Now along with the version of our internal tool you will get the version of piptools even though piptools does not ship a __version__ variable.

Fin #

In the end, I am glad I learned that its so easy to use the more accurate package metadata, but still appreciate packages shipping __version__ for all of us n00b’s out here.
Check out gum by charmbracelet. It’s a well-crafted project with great potential. A tool for glamorous shell scripts 🎀
Check out crossposter by Mr-Destructive. It’s a well-crafted project with great potential. Crosspost your articles to dev.to, codenewbie.org, medium.com and hashnode.com with a single shellscript / python package

The one reason I switched to arch

The community, that’s it, end of post, roll the credits. I’m a tinkerer I am a tinkerer, I am not going to run a stock desktop manager, mostly becuase that’s just not how my brain works. I need to tweak everything to fit my needs. Grantid I have not spent much time in many full fledged linux desktop environments. They are far more customizable than windows ever will be, I absolutely love that about them. Inevitibly I end up in a situation where I hit a wall, it just won’t do what I want it to do, or my lack of understanding what came wtih it holds me back. minimal I love minimal installs. I love just building up my system from the bottom up with things that I like, I understand, and that I can script. I’m a noob I spend a lot of my time in the terminal. I’d like to think I know how to use a linux command line for software development really well, but there are a lot of things that I still dont know all that well, mostly because I don’t need to. The AUR Arch’s community maintained repo…