Posts tagged: linux
All posts with the tag "linux"
xrandr is a great cli to manage your windows in a linux distro using x11, which is most of them. The issue is that I can never remember all the flags to the command, and if you are using it with something like a laptop using a dock the names of all the displays tend to change every time you redock. This makes it really hard to make scripts that work right every time.
Homepage #
Check out the deresmos/xrandr-manager for more details on it.
installation #
xrander-manager is a python cli application that is simply a nice interface into xrandr. So you must have xrandr already installed, which is generally just there on any x11 window manager, I’ve never had to install it.
As with any python cli that is indended to be used as a global/system level cli application I always install them with pipx. This automates the process of creating a virtual environment for xrandr-manager for me, and does not clutter up my system packages with its dependencies that may eventually clash with another that I want to use.
# prereqs (xrandr, pipx)
pipx install xrandr-manager
set main monitor #
First if your main display is not set to the correct monitor set your main display first.
xrandr-manager -m HDMI-0
xrandr-manager -m DP-0
prompt mode #
If you dont know the name of your monitors and and don’t want to dig through
xrandr, you can just run --prompt and tab complete to fill set your main
display.
xrandr-manager --prompt
direction #
This is what I most often use xrandr-manager for. Once you have the main display set you can tell it where to put the other monitor. I’ve only tried this with two monitors, I have no idea what happens with more monitors.
xrandr-manager -d right
xrandr-manager -d left
xrandr-manager -d above
xrandr-manager -d below
mirror #
One thing that I always need to jump through hoops to do is mirror. Occasionally I want to mirror so that more people can see the screen while we are split screen gaming. This has seemed like a pain in any other xrandr utility, but trivial in xrandr-manager.
xrandr-manager --mirror
It logs out the xrandr command #
One nice thing about xrandr-manager is that it echos out the xrandr command that it’s running. This is nice because you can toss this behind a hotkey or an init script.
Guis #
Ya there are guis that do this. I’ve had good luck with arandr. It’s more intuitive to drag windows around like what you would do in windows. Every once in awhile it messes up and my polybar overlaps my windows, or my windows end up only on half the screen.
There are also graphics card specific utilities, Ive used nvidia x server settings and it mostly works similar to arandr.
I really like the super clean look of no status menus, no url bar, no bookmarks
bar, nothing. Don’t get me wrong these things are useful, but honestly they
take up screen real estate and I RARELY look at them. What I really want is a
toggle hotkey. I found this one from one of DT’s youtube video’s. I can now
tap xx and both the status bar at the botton and the address bar at the top
disappear.
# ~/.config/qutebrowser/config.py
config.bind("xb", "config-cycle statusbar.show always never")
config.bind("xt", "config-cycle tabs.show always never")
config.bind(
"xx",
"config-cycle statusbar.show always never;; config-cycle tabs.show always never",
)
I recently was unable to boot into my home Linux Desktop, it got stuck at
diskcheck fsck. I found that I was able to get in to a tty through a hotkey.
https://twitter.com/_WaylonWalker/status/1512281106120384519
What’s a TTY? #
There’s probably more to it, but to me its a full screen terminal with zero gui, not even your gui fonts. It does log into your default shell so if you have a comfy command line setup it will be here for you even though it looks much different without fonts and full colorspace.
Normal setup #
Normally you have 6 TTY’s running, the first is dedicated to your desktop manager, which is your login screen it might be something like gdm or lightdm.
- ctrl+alt+F1: login screen
- ctrl+alt+F2: Desktop
- ctrl+alt+F3: TTY 3
- ctrl+alt+F4: TTY 4
- ctrl+alt+F5: TTY 5
- ctrl+alt+F6: TTY 6
In my case the desktop manager neverstarted, so ctrl+alt+F1 brought me into a tty.
What happened?? #
Well after getting back in and having some time to reflect, I think my Desktop manager was installed or just broken, possibly during a update I ran a few days prior.
I tried a bunch of things like switching to lightdm, and manually running startx.
Getting back in #
The final commands that ended up getting me back in were installing and starting gdm3.
sudo apt install gdm3
sudo systemctl start gdm3
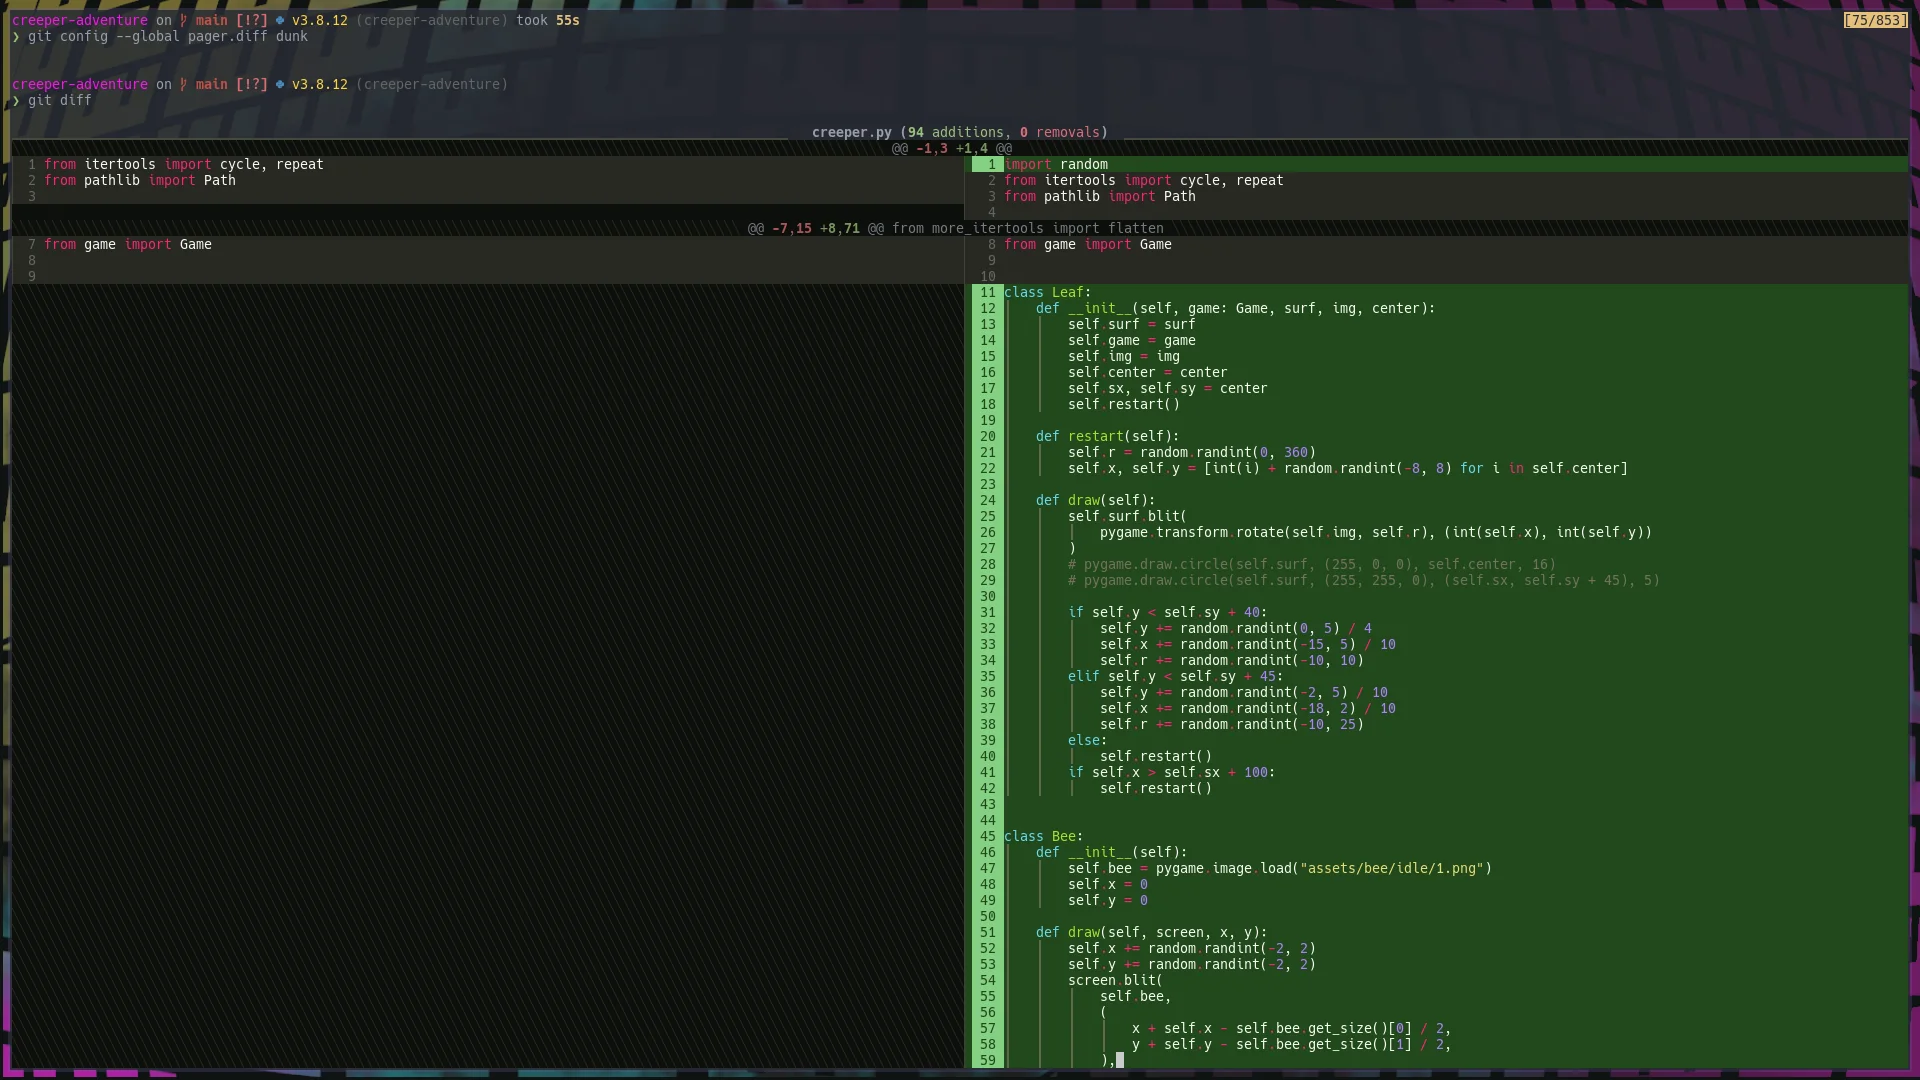
Dunk is a beautiful git diff tool built on top of rich.
Browsing through twitter the other day I discovered it through this tweet by _darrenburns.
https://twitter.com/_darrenburns/status/1510350016623394817
Dunk is beta #
Before I dive in deep, I do want to mention that Dunk is super new and beta at this point. I am making it my default pager, because I know what I am doing and can quickly shift back if I need to, no sweat. If you are a little less comfortable with the command line, terminal, or reading any issues that might come up, it might be best if you just pipe into Dunk when you want to use it.
The author really cautions the use of it as your default pager this early, I’m just showing that it’s possible, and I’m trying it.
He notes that it might have some issues especially with partially staged files.
try it #
You can try it with pipx.
git diff | pipx run dunk
install it #
If you like it, you can install it with pip or pipx, I prefer pipx for cli applications like this.
pipx install dunk
set it as your default pager #
You can configure dunk as your default pager with the command line, or
by editing your .gitconfig file.
git config --global pager.diff "dunk | less -R`
[pager]
diff = dunk | less -R
As pointed out by _darrenburns dunk is not a pager and you can gain back all of the benefits of using a pager by piping into less with the
-Rflag.
reset it if you don’t like it #
You can --unset your pager configuration from the command line or edit
your .gitconfig file by hand to remove the lines shown above.
git config --global --unset pager.diff
Comparison #
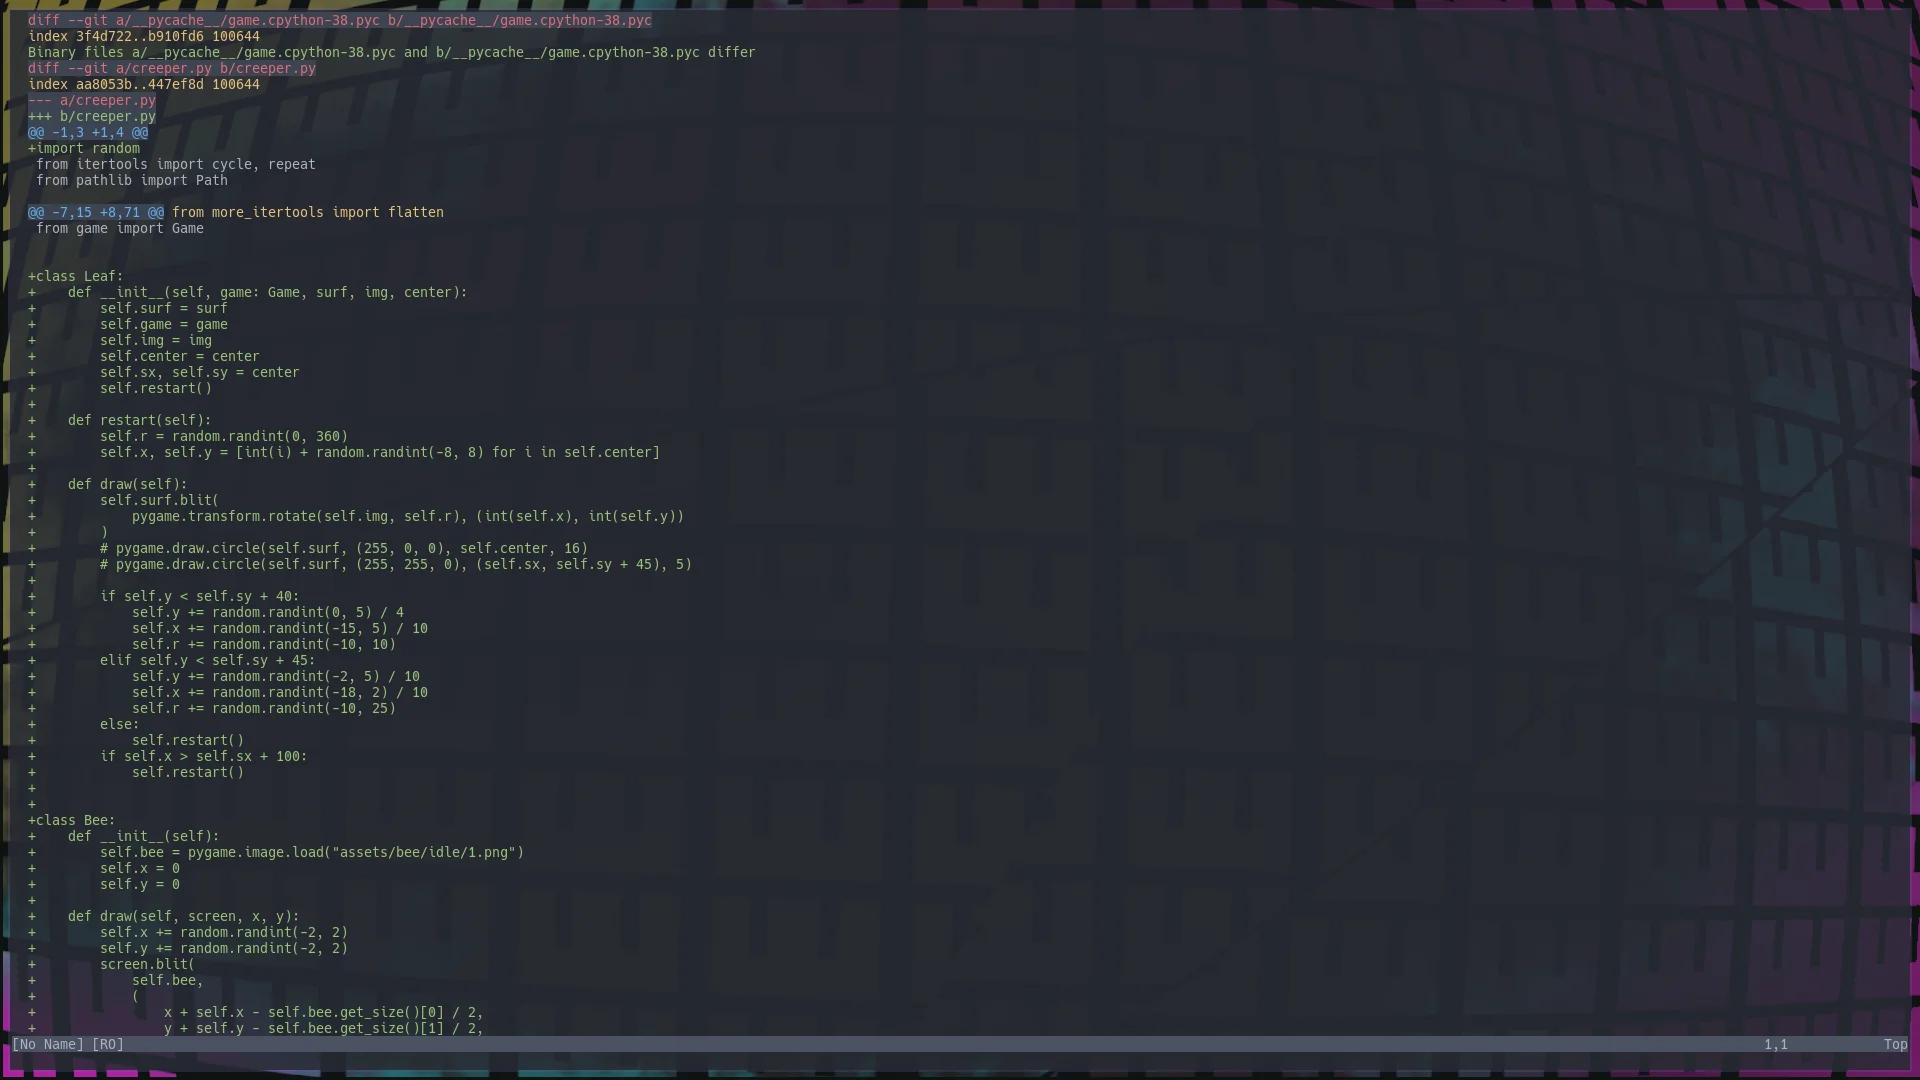
I have some edits to a game my son and I are working on unstaged so I
ran git diff on that project with and without dunk to compare the
differences.
Dunk just looks so good.
Always install #
If you follow along here often you know that I am a big fan of installing all my tools in an ansible playbook so that I don’t suffer configuring a new machine for months after getting it and wondering why its not exactly like the last.
# Dunk - prettier git diffs
# https://github.com/darrenburns/dunk
- name: check is dunk installed
shell: command -v black
register: dunk_exists
ignore_errors: yes
- name: install dunk
when: dunk_exists is failed
shell: pipx install dunk
Installing packages with ansible only if they do not exist
More on conditionally installing tools with ansible in this post.
This morning I was trying to install a modpack on my minecraft server after getting a zip file, and its quite painful when I unzip everything in the current directory rather than the directory it belongs in.
I had the files on a Windows Machine #
So I’ve been struggling to get mods installed on linux lately and the easiest
way to download the entire pack rather than each mod one by one seems to be to
use the overwolf application on windows. Once I have the modpack I can start
myself a small mod-server by zipping it, putting it in a mod-server directory
and running a python http.server
python -m http.server
Downoading on the server #
Then I go back to my server and download the modpack with wget.
wget 10.0.0.171:8000/One%2BBlock%2BServer%2BPack-1.4.zip
Unzip to the minecraft-data directory #
Now I can unzip my mods into the minecraft-data directory.
unzip One+Block+Server+Pack-1.4.zip -d minecraft-data
Running the server with docker #
I run the minecraft server with docker, which is setup to mount the minecraft-data directory.
Running a Minecraft Server in Docker
A bit more on that in the other post, but when I download the whole modpack like this I make these changes to my docker compose. (commented out lines)
version: "3.8"
services:
mc:
container_name: walkercraft
image: itzg/minecraft-server:java8
environment:
EULA: "TRUE"
TYPE: "FORGE"
VERSION: 1.15.2
# MODS_FILE: /extras/mods.txt
# REMOVE_OLD_MODS: "true"
tty: true
stdin_open: true
restart: unless-stopped
ports:
- 25565:25565
volumes:
- ./minecraft-data:/data
# - ./mods.txt:/extras/mods.txt:ro
volumes:
data:
If you ever end up on a linux machine that just does not have enough ram to suffice what you are doing and you just need to get the job done you can give it some more swap. You can look up reccomendations for how much swap you should have this is more about just trying to get your job done when you are almost there, but running out of memory on the hardware you have.
make the /swap file #
You can put this where you wish, for this example I am going to pop it into
/swap
sudo fallocate -l 4G /swap
sudo chmod 600 /swap
sudo mkswap /swap
sudo swapon /swap
make sure that your swap is on #
You can make sure that your swap is working by using the free command, I like
using the -h flag to get human readable numbers.
❯ free -h
total used free shared buff/cache available
Mem: 15Gi 5.5Gi 4.9Gi 458Mi 5.2Gi 9.3Gi
Swap: 4.0Gi 0B 4.0Gi
Reclaim memory usage in Jupyter
I also used this trick in this article to give my python process a bit more oompf and get it on home.
yq is a command line utility for parsing and querying yaml, like jq does for json.
This is for me #
I love that all of these modern tools built in go and rust, just give you a
zipped up executable right from GitHub releases, but it’s not necessarily
straight forward how to install them. yq does one of the best jobs I have
seen, giving you instructions on how to get a specific version and install it.
I use a bunch of these tools, and for what its worth I trust the devs behind them to make sure they don’t break. This so far has worked out well for me, but if it ever doesn’t I can always pick an older version.
Just give me the latest #
Since I am all trusting of them I just want the latest version. I do not want to update a shell script with new versions, or even care about what then next version is, I just want it. Luckily you can script the release page for the latest version on all that I have came accross.
What is the latest #
I wrote or stole, I think I wrote it, this line of bash quite awhile ago, and it has served me well for finding the latest release for any GitHub project using releases. Just update it with the name of the tool, org, and repo and it works.
YQ_VERSION=$(curl --silent https://github.com/mikefarah/yq/releases/latest | tr -d '"' | sed 's/^.*tag\///g' | sed 's/>.*$//g' | sed 's/^v//')
Install with your shell #
Now that we know how to consistently get the right version, I generally right
click the release in the releases page, replace the version with
${TOOL_VERSION} and put it in this wget call, then move the binary over to ~/.local/bin
local tmp=`mktemp -dt install-XXXXXX`
pushd $tmp
YQ_VERSION=$(curl --silent https://github.com/mikefarah/yq/releases/latest | tr -d '"' | sed 's/^.*tag\///g' | sed 's/>.*$//g' | sed 's/^v//')
wget https://github.com/mikefarah/yq/releases/download/v${YQ_VERSION}/yq_linux_amd64.tar.gz -O- -q | tar -zxf - -C /tmp
cp yq_linux_amd64 ~/.local/bin/yq
popd
Install with ansible #
Now I don’t want to worry about missing yq again, so I am added it to my
ansible install script. This way it’s installed everyt time I setup a new
system with all of my favorite cli’s.
- name: check is yq installed
shell: command -v yq
register: yq_exists
ignore_errors: yes
tags:
- yq
- name: Install yq
when: yq_exists is failed
shell: |
local tmp=`mktemp -dt install-XXXXXX`
pushd $tmp
YQ_VERSION=$(curl --silent https://github.com/mikefarah/yq/releases/latest | tr -d '"' | sed 's/^.*tag\///g' | sed 's/>.*$//g' | sed 's/^v//')
wget https://github.com/mikefarah/yq/releases/download/v${YQ_VERSION}/yq_linux_amd64.tar.gz -O- -q | tar -zxf - -C /tmp
cp yq_linux_amd64 {{ lookup('env', 'HOME') }}/.local/bin/yq
popd
tags:
- yq
Links #
This is how I installed it, of course you can always follow Mike’s instructions from the repo.
So worktrees, I always thought they were a big scary things. Turns out they are much simpler than I thought.
Myth #1 #
no special setup
I thought you had to be all in or worktrees or normal git, but not both. When I see folks go all in on worktrees they start with a bare repo, while its true this is the way you go all in, its not true that this is required.
Lets make a worktree #
Making a worktree is as easy as making a branch. It’s actually just a branch that lives in another place in your filesystem.
# checkout a new worktree called compare based on main in /tmp/project
git worktree add -b compare /tmp/project main
# checkout a new worktree called compare based on HEAD in /tmp/project
git worktree add -b compare /tmp/project
# checkout a worktree from an existing feature branch in /tmp/project
git worktree add /tmp/project my-existing-feature-branch
The worktree that you create is considered a linked worktree, while the original worktree is called the main worktree
Note that I put this in my tmp directory because I don’t expect it to live very long, my recent use case was to compare two files after a big formatting change. You put these where you want, but dont come at me when your /tmp gets wiped and you loose work.
Myth #2 #
they are hidden mysterious creatures
Just like branches git has some nice commands to help us understand what worktrees we have on our system. Firstly we have something very specific to worktrees to list them out.
git worktree list
gives the output
/home/u_walkews/git/git-work-play b202442 [main]
/tmp/another d9b2cf1 [another]
Even the branch command gives a bit different output for a worktree.
git branch
gives this output, notice the + denotes an actively linked worktree, and the * gives the active branch. If you cd over to the worktree directory, these will switch roles.
+ another
just-a-branch
* main
You can only checkout a branch in one place #
If you try to checkout a branch that is checked out in a linked worktree, you will be presented with an error, and it will not let you check out a second copy of that branch.
❯ git checkout another
fatal: 'another' is already checked out at '/tmp/another'
Myth #3 #
once you go worktree, you worktree
Once you have worktrees on your system, you have a few ways to get rid of them.
Using git’s way feels much superior, but if your a doof like me and didn’t read
the manual before you rm /tmp/another -rf you will notice that the worktree
is still active. If you run git worktree prune it will clean that right up.
git worktree remove another
rm /tmp/another
git worktree prune
It won’t let you remove if you have changes #
This makes me think that remove is a much safer option. If you have
uncommitted changes, git worktree remove will throw an error, and make you
commit or use --force to remove the worktree.
❯ git worktree remove another
fatal: 'another' contains modified or untracked files, use --force to delete it
RTFM #
read the friendly manual
There is a ton more information in the man page for worktrees, these are just the parts that seemed really useful to me out of the gate.
man git worktree
I write many of these posts from a 10 year old desktop that sits in my office these days. It does a very fine job running all of the things I need it to for my side work, but sometimes I want a mobile setup. I don’t really want to spend the $$ on a new laptop just for the few times I want to be somewhere else in the house. What I do have though is a chromebook.
I’ve tried to get the chromebook into my workflow in the past, but have failed. Much because by the time I got all of my tools up and running in the linux vm it was taking up quite a bit of space on the device and made it harder for others to use as a chromebook.
Today I am giving it a second try, but this time with ssh.
Checking for existing sshd #
Before doing anything I checked to see if sshd is already running. Using the following command.
sudo service ssh status
# or
pgrep -l sshd
Both returned nothing so I know that its not running.
setting up sshd #
just apt install it
Next install the openssh-client and openssh-server
sudo apt install openssh-client -y
sudo apt install openssh-server -y
After this I can see that its now running by checking its status once again.
sudo service ssh status
Gives me the result.
● ssh.service - OpenBSD Secure Shell server
Loaded: loaded (/lib/systemd/system/ssh.service; enabled; vendor preset: enabled)
Active: active (running) since Tue 2022-03-08 08:17:05 CST; 12min ago
Docs: man:sshd(8)
man:sshd_config(5)
Process: 181185 ExecStartPre=/usr/sbin/sshd -t (code=exited, status=0/SUCCESS)
Main PID: 181189 (sshd)
Tasks: 1 (limit: 19119)
Memory: 2.8M
CPU: 96ms
CGroup: /system.slice/ssh.service
└─181189 sshd: /usr/sbin/sshd -D [listener] 0 of 10-100 startups
Accessing the desktop #
I have already enabled the Linux terminal on my chromebook, so I just opened the terminal, and ran the following.
ssh <username>@<ip-address>
It prompted for my password and I was in. I had all of my vim, tmux, and zsh comforts that I enjoy without installing anything. It worked so well that this whole post was written from my chromebook.
Limitations #
This does limit me to being on the same network as my desktop, which these days is almost always true.
ssh keys #
Out of the box I am just using passwords to get in, but if this were public I would lock down to requiring an ssh key to enter. I’ll likey do this in a future post.
If you have ever ran which <command> and see duplicate entries it’s likely
that you have duplicate entries in your $PATH. You can clean this up with a
one liner at the end of your bashrc or zshrc.
eval "typeset -U path"
There is GNU coreutils command called mktemp that is super handy in shell
scripts to make temporary landing spots for files so that they never clash with
another instance, and will automatically get cleaned up when you restart, or
whenever /tmp gets wiped. I’m not sure when that is, but I don’t expect it
to be long.
Making temp directories #
Here are some examples of making temp directories in different places, my
favorite is mktemp -dt mytemp-XXXXXX.
# makes a temporary directory in /tmp/ with the defaul template tmp.XXXXXXXXXX
mktemp
# makes a temporary directory in your current directory
mktemp --directory mytemp-XXXXXX
# shorter version
mktemp -d mytemp-XXXXXX
# same thing, but makes a file
mktemp mytemp-XXXXXX
# makes a temporary directory in your /tmp/ directory (or what ever you have configured as your TMPDIR)
mktemp --directory --tmpdir mytemp-XXXXXX
# shorter version
mktemp -dt mytemp-XXXXXX
# same thing, but makes a file
mktemp --tmpdir mytemp-XXXXXX
# shorter version
mktemp -t mytemp-XXXXXX
Use Case #
Here is a sample script that shows how to capture the tempdir as a variable and reuse it. Here is an example of curling my bootstrap file into a temp directory and running it from that directory.
local tmp=`mktemp -dt bootstrap-XXXXXX`
pushd $tmp
curl https://raw.githubusercontent.com/WaylonWalker/devtainer/main/bootstrap > bootstrap
bash bootstrap
popd
Templates #
You must have at least 3 trailing X’s that mktemp will replace with random characters. I played with it for a bit, it kinda allows for some trailing characters, and will not fill groups of X’s earlier in your template, only the last consecutive string.
My randomm samples I played with.
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com) took 2m24s
❯ mktemp myXtemp-XaXbXXXX -dt
/tmp/myXtemp-XaXbx9hn
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XaXbXXXXs -dt
/tmp/myXtemp-XaXb2tpGs
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XaXbXXcXXs -dt
mktemp: too few X's in template ‘myXtemp-XaXbXXcXXs’
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XaXbXXcXXs -dt
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XaXbXXXXt -dt
/tmp/myXtemp-XaXbe8PWt
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XXX-you-XXX -dt
/tmp/myXtemp-XXX-you-48l
waylonwalker.com on main [!?] v3.9.7 (waylonwalker.com)
❯ mktemp myXtemp-XXX-you-XX -dt
mktemp: too few X's in template ‘myXtemp-XXX-you-XX’
RTFM #
The man page has good stuff on all the flags that you might need.
man mktemp
Once you give a branch the big D (git branch -D mybranch) its gone,
its lost from your history. It’s completely removed from your log.
There will be no reference to these commits, or will there?
TLDR #
Checkout is your savior, all you need is the commit hash.
Immediate Regret #
your terminal is still open
We have all done this, you give branch the big D only to realize it was the wrong one. Don’t worry, not all is lost, this is the easiest to recover from. When you run the delete command you will see something like this.
❯ git branch -D new
Deleted branch new (was bc02a64).
Notice the hash is right there is the hash of your commit. You can use that to get your content back.
git checkout -b bc02a64
git branch new
# or in one swoop checkout your new branch at the `start-point` you want
git checkout -b new bc02a64
Delayed reaction #
you have closed your terminal
If you have closed your terminal, or have deleted with a gui or something that does not tell you the hash as you run it, don’t fret, all your work is still there (as long as you have commited). You just have to dig it out. The reflog contains a list of all git operations that have occurred on your git repo, and can be incredibly helpful with this.
Kinda Recent #
If your botched delete operation was recent just diving right into the reflog will show it.
❯ git reflog
03a3338 (main) HEAD@{0}: checkout: moving from new to main
bc02a64 (HEAD -> another, new) HEAD@{4}: commit: newfile
03a3338 (main) HEAD@{2}: checkout: moving from main to new
In this example, I checked out a branch called new, commited a new file, then switched back to main and deleted new.
Now That I have the commit hash I can use the same solution to get my branch back.
git checkout -b bc02a64
git branch new
# or in one swoop checkout your new branch at the `start-point` you want
git checkout -b new bc02a64
A lot has happened since then #
If a lot has happened since then, you are going to need to pull out some
more tool to sift through that reflog, especially if its a big one.
The first suggestion that I have is to pipe into grep and look for
commit messages, or the name of the branch.
❯ git reflog | grep "moving from"
03a3338 HEAD@{1}: checkout: moving from main to branch/oops
03a3338 HEAD@{2}: checkout: moving from oops to main
03a3338 HEAD@{4}: checkout: moving from main to oops
03a3338 HEAD@{5}: checkout: moving from another to main
bc02a64 HEAD@{6}: checkout: moving from main to another
03a3338 HEAD@{7}: checkout: moving from another to main
bc02a64 HEAD@{8}: checkout: moving from new to another
bc02a64 HEAD@{9}: checkout: moving from bc02a64bbe5683d905e333e8dfcbbb91a5e77549 to new
bc02a64 HEAD@{10}: checkout: moving from main to bc02a64bbe56
03a3338 HEAD@{11}: checkout: moving from new to main
03a3338 HEAD@{13}: checkout: moving from main to new
03a3338 HEAD@{14}: checkout: moving from other to main
03a3338 HEAD@{18}: checkout: moving from main to other
git has a built in --grep flag, but I don’t think there is a way to
filter by branch name, regardless it still is helpful.
❯ git reflog --grep new
bc02a64 (HEAD -> another, new) HEAD@{4}: commit: newfile
Maybe if you can remember a filename you can pass in -- <filename>.
git reflog -- readme.md
RTFM #
There are many other ways to slice up a git log, and reflog alike. check
out man git log for some more flags.
Big announcement recently that obs studio now builds out to a flatpak, hopefully making it easier for all of us to install, especially us near normies that don’t regularly compile anything from source.
install flatpak #
I did not have flatpak installed so the first thing I had to do was get
the flatpak command installed, and add their default repo.
sudo apt install flatpak
flatpak remote-add --if-not-exists flathub https://flathub.org/repo/flathub.flatpakrepo
Once I had flatpak, I was able to get obs installed with the following command.
flatpak install flathub com.obsproject.Studio
Once Installed it fired right up for me with the next command they suggested.
flatpak run com.obsproject.Studio
It Works #
Pretty straightforward, following the instructions given it all worked for me, but it was missing a lot of the plugins that the current snap package I am using gives me (namely virtual webcam). So I am not ready to jump onto it until I figure out how to manage my own obs plugins. For now I think the snap is working just well enough.
Links #
Anyone just starting out their vim customization journey is bound to run into this error.
E5520: <Cmd> mapping must end with <CR>
I did not get it #
I’ll admit, in hindsight it’s very clear what this is trying to tell me, but for whatever reason I still did not understand it and I just used a : everywhere.
From the docs #
If you run :h <cmd> you will see a lot of reasons why you should do it, from
performance, to hygene, to ergonomics. You will also see another clear
statement about how to use <cmd>.
E5520
<Cmd> commands must terminate, that is, they must be followed by <CR> in the
{rhs} of the mapping definition. Command-line mode is never entered.
When to map with a : #
You still need to map your remaps with a : if you do not close it with a
<cr>. This might be something like prefilling a command with a search term.
nnoremap <leader><leader>f :s/search/
Otherwise use #
If you can close the <cmd> with a <cr> the command do so. Your map will
automatically be silent, more ergonomic, performant, and all that good stuff.
nnoremap <leader><leader>f <cmd>s/search/Search/g<cr>
One thing about moving to a tiling window manager like awesome wm or i3 is that
they are so lightweight they are all missing things like bluetooth gui’s out of
the box, and you generally bring your own. Today I just needed to connet a new
set of headphones, so I decided to just give the bluetoothctl cli a try. It
seems to come with Ubuntu, I don’t think I did anything to get it.
bluetoothctl
Running bluetoothctl pops you into a repl/shell like bah, python, or ipython.
From here you can execute bluetoothctl commands.
Here is what I had to do to connect my headphones.
# list out the commands available
help
# scan for new devices and stop when you see your device show up
scan on
scan off
# list devices
devices
paired-devices
# pair the device
pair XX:XX:XX:XX:XX:XX
# now your device should show up in the paired list
paired-devices
# connet the device
connect XX:XX:XX:XX:XX:XX
help #
Here is the output of the help menu on my machine, it seems pretty straight forward to block, and remove devices from here.
note ctrl revers to the bluetooth controller on the machine you are on, and dev refers to a device id.
Menu main:
Available commands:
-------------------
advertise Advertise Options Submenu
scan Scan Options Submenu
gatt Generic Attribute Submenu
list List available controllers
show [ctrl] Controller information
select <ctrl> Select default controller
devices List available devices
paired-devices List paired devices
system-alias <name> Set controller alias
reset-alias Reset controller alias
power <on/off> Set controller power
pairable <on/off> Set controller pairable mode
discoverable <on/off> Set controller discoverable mode
agent <on/off/capability> Enable/disable agent with given capability
default-agent Set agent as the default one
advertise <on/off/type> Enable/disable advertising with given type
set-alias <alias> Set device alias
scan <on/off> Scan for devices
info [dev] Device information
pair [dev] Pair with device
trust [dev] Trust device
untrust [dev] Untrust device
block [dev] Block device
unblock [dev] Unblock device
remove <dev> Remove device
connect <dev> Connect device
disconnect [dev] Disconnect device
menu <name> Select submenu
version Display version
quit Quit program
exit Quit program
help Display help about this program
Final Impressions #
This was something that I have never used, and thought it would be intimidating but it worked great first try out of the box. It could have been my device on the other end, but this was one of the least frustrations I have had pairing a new device.
Samba is an implementation of the smb protocol that allows me to setup network shares on my linux machine that I can open on a variety of devices.
I think the homelab is starting to intrigue me enought to dive into the path of experimenting with different things that I might want setup in my own home. One key piece of this is network storage. As I looked into nas, I realized that it takes a dedicated machine, or one virtualized at a lower level than I have capability for right now.
Humble Beginnings #
To get goind I am going to make a directory /srv/samba/public open to anyone
on my network. I am not going to worry too much about it, I just want
something up and running so that I can learn.
Install samba, open the firewall, and edit the smb.conf
sudo apt install samba samba-common-bin
sudo ufw allow samba
sudo nvim /etc/samba/smb.conf
I added this to the end of my smb.conf
[public]
comment = public share, no need to enter username and password
path = /srv/samba/public/
browseable = yes
writable = yes
guest ok = yes
Then I made the /srv/samba/public directory and made it writable by anyone.
sudo mkdir -p /srv/samba/public
sudo setfacl -R -m "u:nobody:rwx" /srv/samba/public/
Windows, yes windows #
I have a windows desktop in my office, primarily for my wife to run premiere
pro, and my son to play Minecraft. I walked over to it, opened the file
explorer, and ernt to \\<my-local-ip>. It asked for the username and
password, I typed in the username and password of the linux device I have the
share running on, and I was in. Right there I could see the Public folder. I
opened it and made a files successfully.
A super useful tool when doing PR’s or checking your own work during a big
refactor is the silver searcher. Its a super fast command line based searching
tool. You just run ag "<search term>" to search for your search term. This
will list out every line of every file in any directory under your current
working directory that contains a match.
Ahead/Behind #
It’s often useful to need some extra context around the change. I recently
reviewed a bunch of PR’s that moved schema from save_args to the root of the
dataset in all yaml configs. To ensure they all made it to the top level
DataSet configuraion, and not underneath save_args. I can do a search for all
the schemas, and ensure that none of them are under save_args anymore.
ag "schema: " -A 12 -B 12
Installing rust in your own ansible playbook will make sure that you can get consistent installs accross all the machines you may use, or replicate your development machine if it ever goes down.
Personal philosophy #
I try to install everything that I will want to use for more than just a trial inside of my ansible playbook. This way I always get the same setup across my work and home machines, and anytime I might setup a throw away vm.
reccommended install #
This is how rust reccomends that you install it on Ubuntu. First update your system, then run their installer, and finally check that the install was successful.
# system update
sudo apt update
sudo apt upgrade
# download and run the rust installer
curl https://sh.rustup.rs -sSf | sh
# confirm your installation is successful
rustc --version
Ansible Install #
The first thing I do in my playbooks is to check if the tool is already
installed. Here I chose to look for cargo, you could also look for
rustc.
- name: check if cargo is installed
shell: command -v cargo
register: cargo_exists
ignore_errors: yes
I first check for an existing install so I can re-run my playbooks quickly filling in only missing tools. More on this ansible install conditionally
Next we need to download the installer script and make it executable.
- name: Download Installer
when: cargo_exists is failed
get_url:
url: https://sh.rustup.rs
dest: /tmp/sh.rustup.rs
mode: '0755'
force: 'yes'
tags:
- rust
I chose to download the installer, because I was unable to pass in the
-yflag otherwise, which is required to do unattended installs.
Last we just run the installer given to us by rust with the -y flag so
that it will run unattended.
- name: install rust/cargo
when: cargo_exists is failed
shell: /tmp/sh.rustup.rs -y
tags:
- rust
One more thing #
Make sure that you source your cargo env, otherwise your shell will not
find rustc or cargo. I chose to do this by adding the following
line to my ~/.zshrc. You can but it in ~/.bashrc if that is your
thing, or just run it in your shell to just get it to work.
[ -f ~/.cargo/env ] && source $HOME/.cargo/env
Full Install Playbook #
Here is a fully working install playbook to get you started or to port into your own playbook.
- hosts: localhost
gather_facts: true
become: true
become_user: "{{ lookup('env', 'USER') }}"
pre_tasks:
- name: update repositories
apt: update_cache=yes
become_user: root
changed_when: False
vars:
user: "{{ ansible_user_id }}"
tasks:
- name: check if cargo is installed
shell: command -v cargo
register: cargo_exists
ignore_errors: yes
- name: Download Installer
when: cargo_exists is failed
get_url:
url: https://sh.rustup.rs
dest: /tmp/sh.rustup.rs
mode: '0755'
force: 'yes'
tags:
- rust
- name: install rust/cargo
when: cargo_exists is failed
shell: /tmp/sh.rustup.rs -y
tags:
- rust
You can save this as a local.yml and run the following in your shell
to run the playbook on your local machine.
ansible-playbook local.yml --ask-become-pass
note:
--ask-become-passis required for the system update step. This will ask for your password as soon as ansible starts.
I also have a very similar article on hwo I ansible install fonts
Calendar data could not load. Try again.